Safety, Alignment & Ethics

68 Items

Safety, alignment, ethics. Proofs of safe AGI. Epistemology of provably safe AGI. Provably Compliant Systems.

All Items

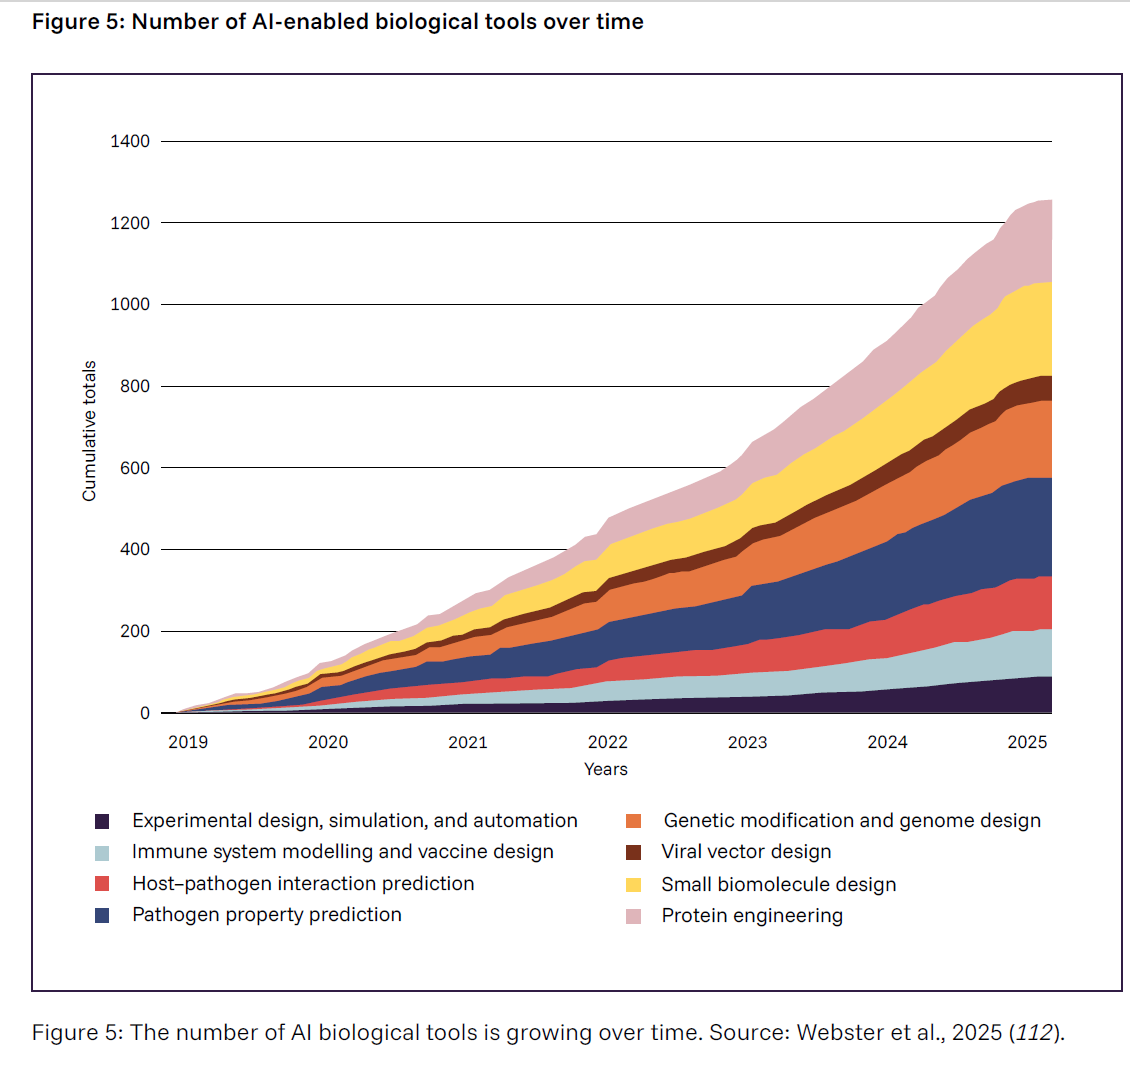
  • International Al Safety Report: First Key Update Capabilities and Risk Implications

    Yoshua Bengio, Stephen Clare, Carina Prunkl, Maksym Andriushchenko, Benjamin Bucknall, Philip Fox, Tiancheng Hu, Cameron Jones, Sam Manning, Nestor Maslej, Vasilios Mavroudis, Conor McGlynn, Malcolm Murray, Shalaleh Rismani, Charlotte Stix, Lucia Velasco, Nicole Wheeler, Daniel Privitera, Sören Mindermann, Daron Acemoglu, Thomas G. Dietterich, Fredrik Heintz, Geoffrey Hinton, Nick Jennings, Susan Leavy, Teresa Ludermir, Vidushi Marda, Helen Margetts, John McDermid, Jane Munga, Arvind Narayanan, Alondra Nelson, Clara Neppel, Sarvapali D. (Gopal) Ramchurn, Stuart Russell, Marietje Schaake, Bernhard Schölkopf, Alvaro Soto, Lee Tiedrich, Gaël Varoquaux, Andrew Yao, Ya-Qin Zhang, Leandro Angelo Aguirre, Olubunmi Ajala, Fahad Albalawi, Noora AlMalek, Christian Busch, André Carlos Ponce de Leon Ferreira de Carvalho, Jonathan Collas, Amandeep Gill, Ahmet Halit Hatip, Juha Heikkilä, Chris Johnson, Gill Jolly, Ziv Katzir, Mary N. Kerema, Hiroaki Kitano, Antonio Krüger, Aoife McLysaght, Oleksii Molchanovskyi, Andrea Monti, Kyoung Mu Lee, Mona Nemer, Nuria Oliver, Raquel Pezoa, Audrey Plonk, José Ramón López Portillo, Balaraman Ravindran, Hammam Riza, Crystal Rugege, Haroon Sheikh, Denise Wong, Yi Zeng, Liming Zhu
    DOI: https://doi.org/10.70777/si.v2i6.16253
  • Why We Might Need Advanced AI to Save Us from Doomers, Rather than the Other Way Around A Review of If Anyone Builds It, Everyone Dies: Why Superhuman AI Would Kill Us All by Eliezer Yudkowsky and Nate Soares

    Preston Estep
    DOI: https://doi.org/10.70777/si.v2i6.16251
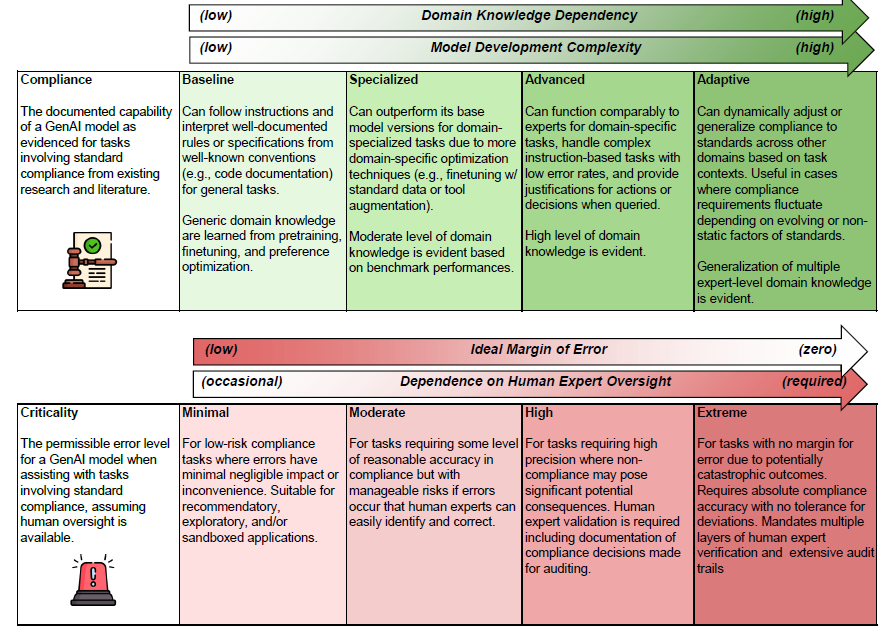
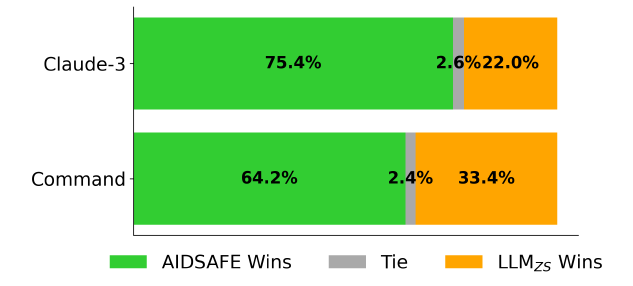
  • Standardizing Intelligence: Aligning Generative AI for Regulatory and Operational Compliance

    Joseph Marvin Imperial, Matthew D. Jones, Harish Tayyar Madabushi
    DOI: https://doi.org/10.70777/si.v2i5.16189
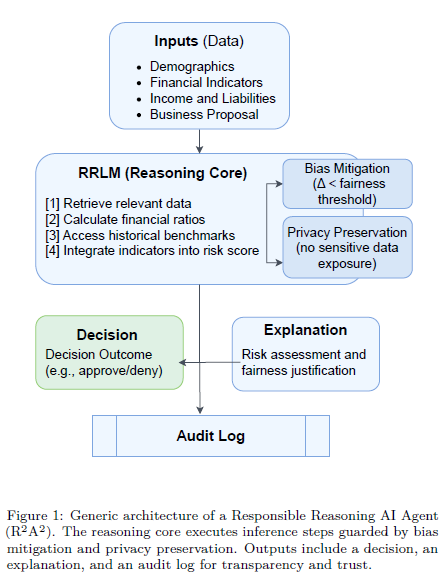
  • Responsible Agentic Reasoning and AI Agents: A Critical Survey Proposal for Safe Agentic AI via Responsible Reasoning AI Agents (R2A2)

    Shaina Raza, Ranjan Sapkota, Manoj Karkee, Christos Emmanouilidis
    DOI: https://doi.org/10.70777/si.v2i6.16169
  • Thinking Isn’t an Illusion Overcoming the Limitations of Reasoning Models via Tool Augmentations

    Zhao Song, Song Yue, Jiahao Zhang
    DOI: https://doi.org/10.70777/si.v2i6.15961
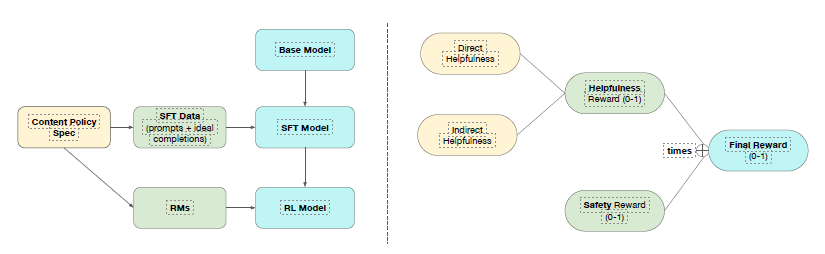
  • From Hard Refusals to Safe-Completions: Toward Output-Centric Safety Training

    Yuan Yuan, Tina Sriskandarajah, Anna-Luisa Brakman, Alec Helyar, Alex Beutel, Andrea Vallone, Saachi Jain
    DOI: https://doi.org/10.70777/si.v2i6.15625
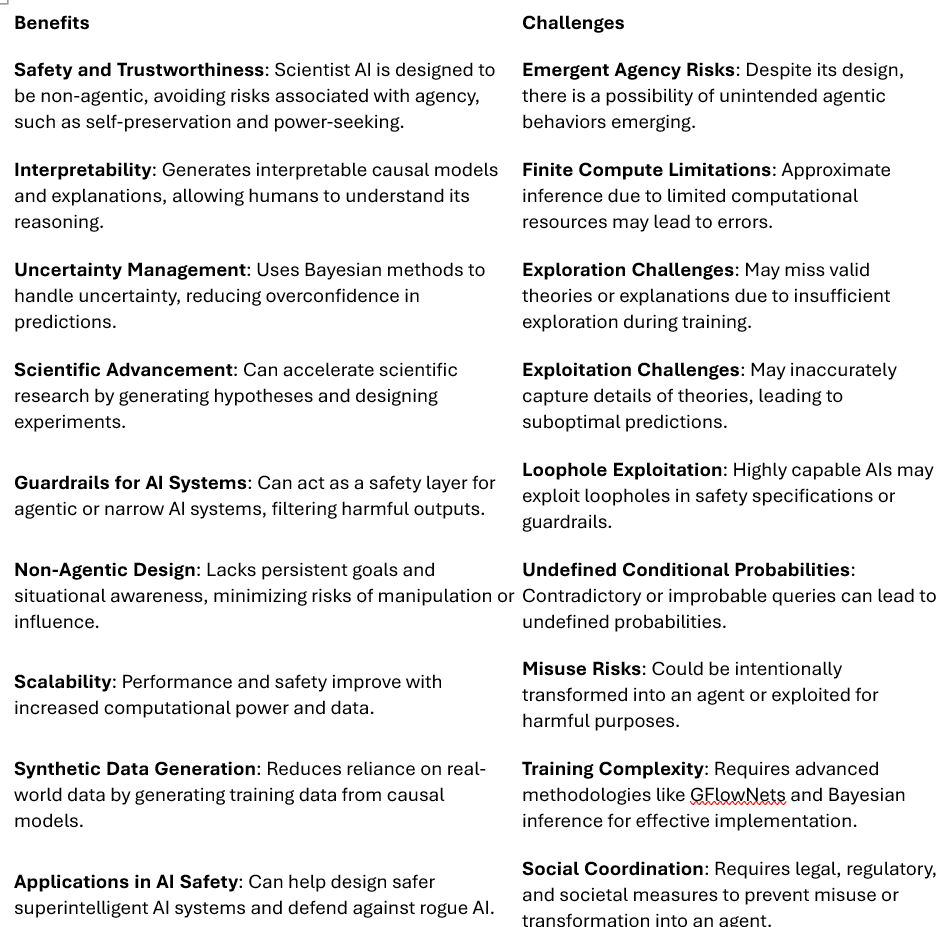
  • Superintelligent Agents Pose Catastrophic Risks: Can Scientist AI Offer a Safer Path?

    Yoshua Bengio, Michael Cohen, Damiano Fornasiere, Joumana Ghosn, Pietro Greiner, Matt MacDermott, Soren Mindermann, Adam Oberman, Jesse Richardson, Oliver Richardson, Marc-Antoine Rondeau, Pierre-Luc St-Charles, David Williams-King
    DOI: https://doi.org/10.70777/si.v2i5.15569
  • Highlights of the Issue: Singapore Consensus – Safety Technology In Progress

    Kris Carlson
    DOI: https://doi.org/10.70777/si.v2i5.15525
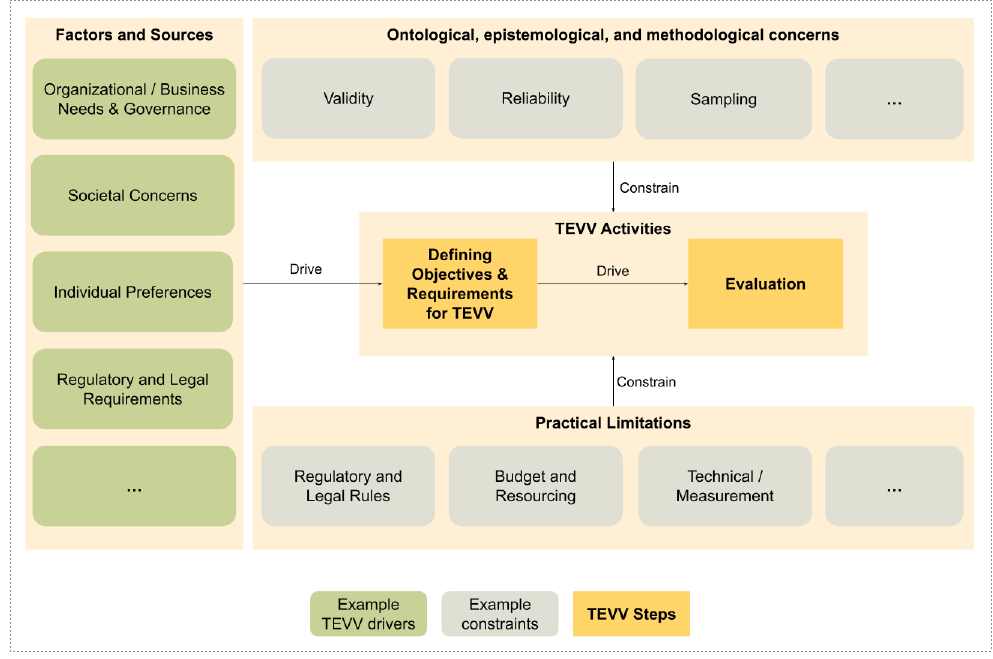
  • Outline: Proposed Zero Draft for a Standard on AI Testing, Evaluation, Verification, and Validation

    NIST
    DOI: https://doi.org/10.70777/si.v2i5.15513
  • America's AI Action Plan Winning the Race

    Office of Science and Technology Policy (OSTP)
    DOI: https://doi.org/10.70777/si.v2i5.15507
  • The Singapore Consensus on Global AI Safety Research Priorities Building a Trustworthy, Reliable and Secure AI Ecosystem

    Yoshua Bengio, Max Tegmark, Stuart Russell, Dawn Song, Sören Mindermann, Lan Xue, Stephen Casper, Luke Ong, Vanessa Wilfred, Tegan Maharaj, Wan Sie Lee, Ya-Qin Zhang
    DOI: https://doi.org/10.70777/si.v2i5.15503
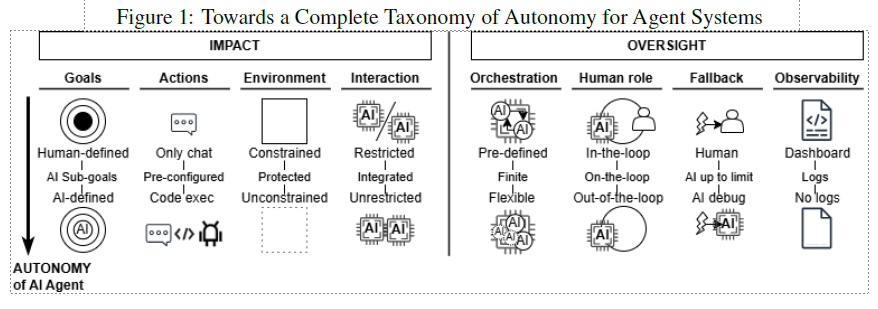
  • Measuring AI Agent Autonomy: Towards a Scalable Approach with Code Inspection

    Peter Cihon, Merlin Stein, Gagan Bansal, Sam Manning, Kevin Xu
    DOI: https://doi.org/10.70777/si.v2i3.15295
  • Timeline to Artificial General Intelligence 2025 – 2030+

    Gil Syswerda
    DOI: https://doi.org/10.70777/si.v2i3.15119
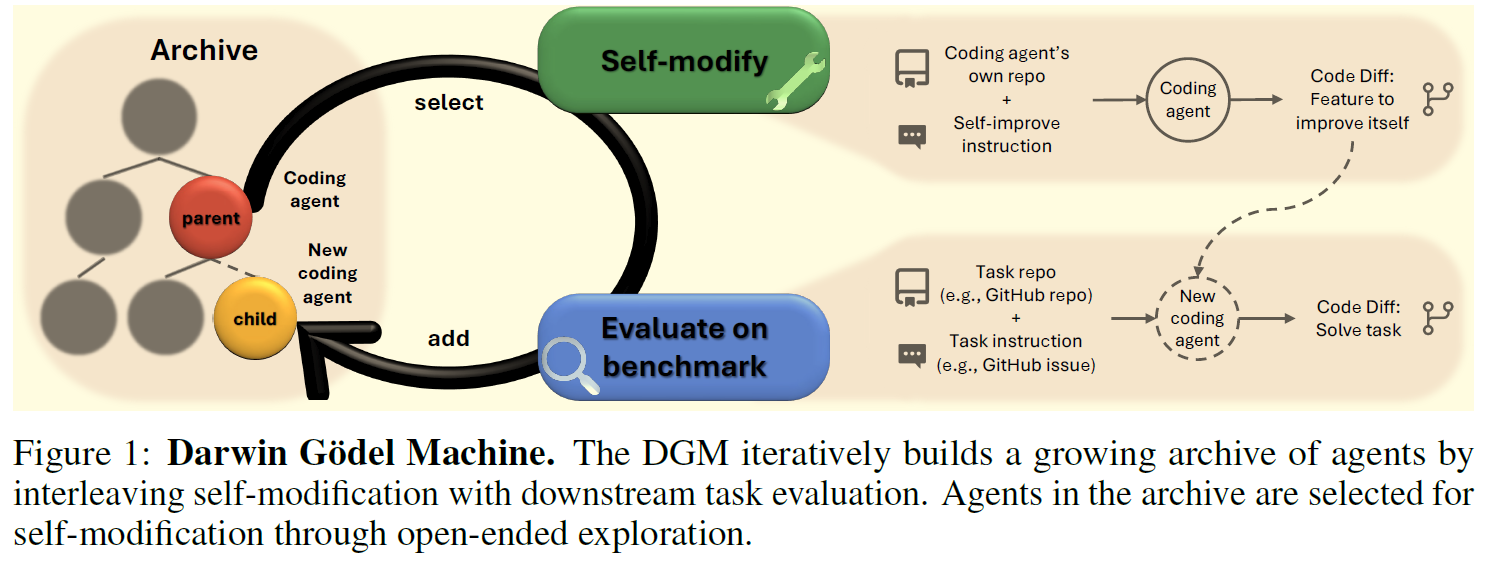
  • Darwin Gödel Machine: Open-Ended Evolution of Self-Improving Agents

    Jenny Zhang, Shengran Hu, Cong Lu, Robert Lange, Jeff Clune
    DOI: https://doi.org/10.70777/si.v2i3.15063
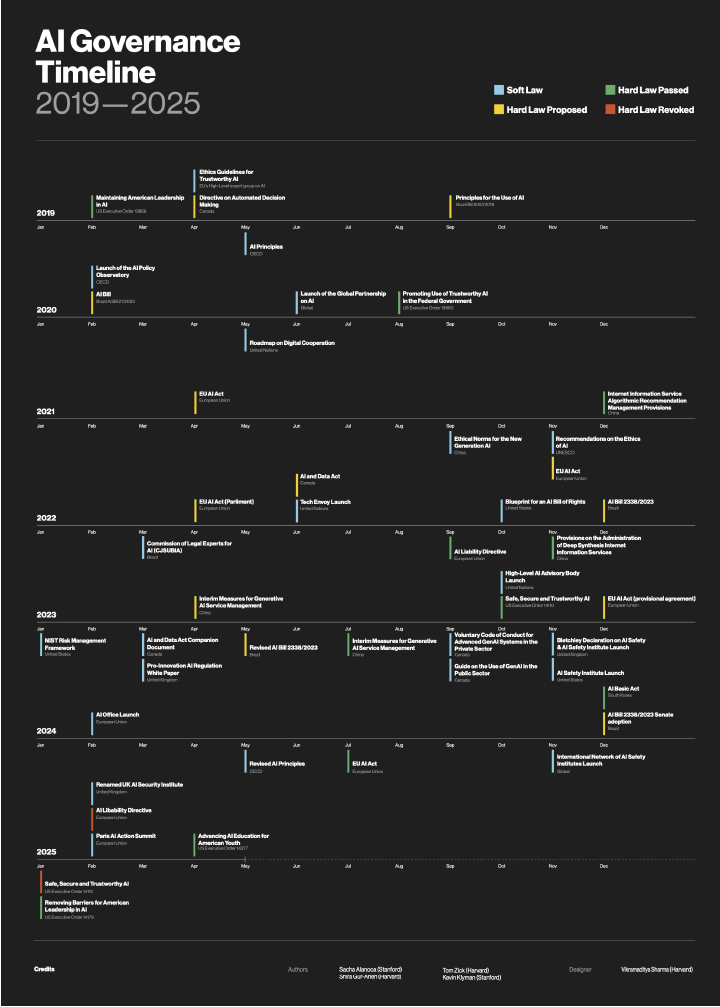
  • Comparing Apples to Oranges: A Taxonomy for Navigating the Global Landscape of AI Regulation

    Sacha Alanoca, Shira Gur-Arieh, Tom Zick, Kevin Klyman
    DOI: https://doi.org/10.70777/si.v2i3.15137
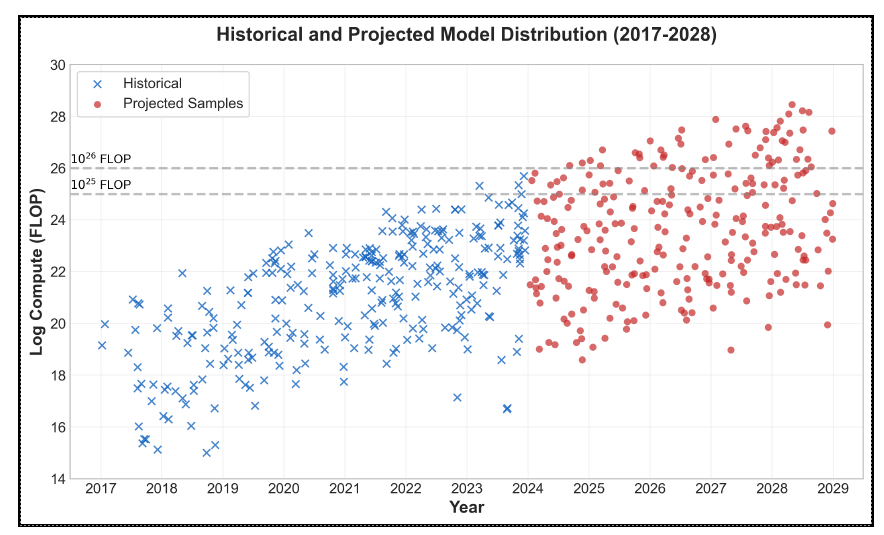
  • Trends in Frontier AI Model Count: A Forecast to 2028

    Iyngkarran Kumar, Sam Manning
    DOI: https://doi.org/10.70777/si.v2i3.15155
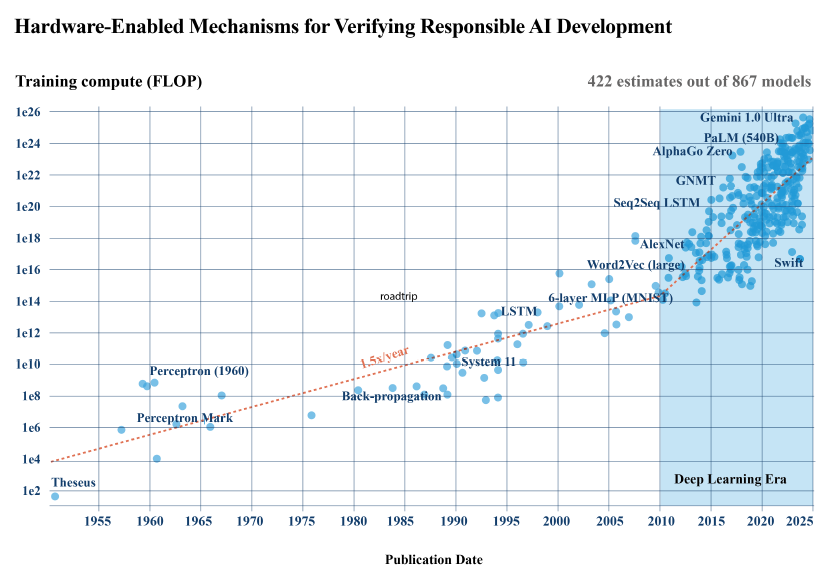
  • Hardware-Enabled Mechanisms for Verifying Responsible AI Development

    Aidan O’Gara, Gabriel, Will Hodgkins, James Petrie, Vincent Immler, Aydin Aysu, Kanad Basu, Shivam Bhasin, Stjepan Picek, Ankur Srivastava
    DOI: https://doi.org/10.70777/si.v2i3.15157
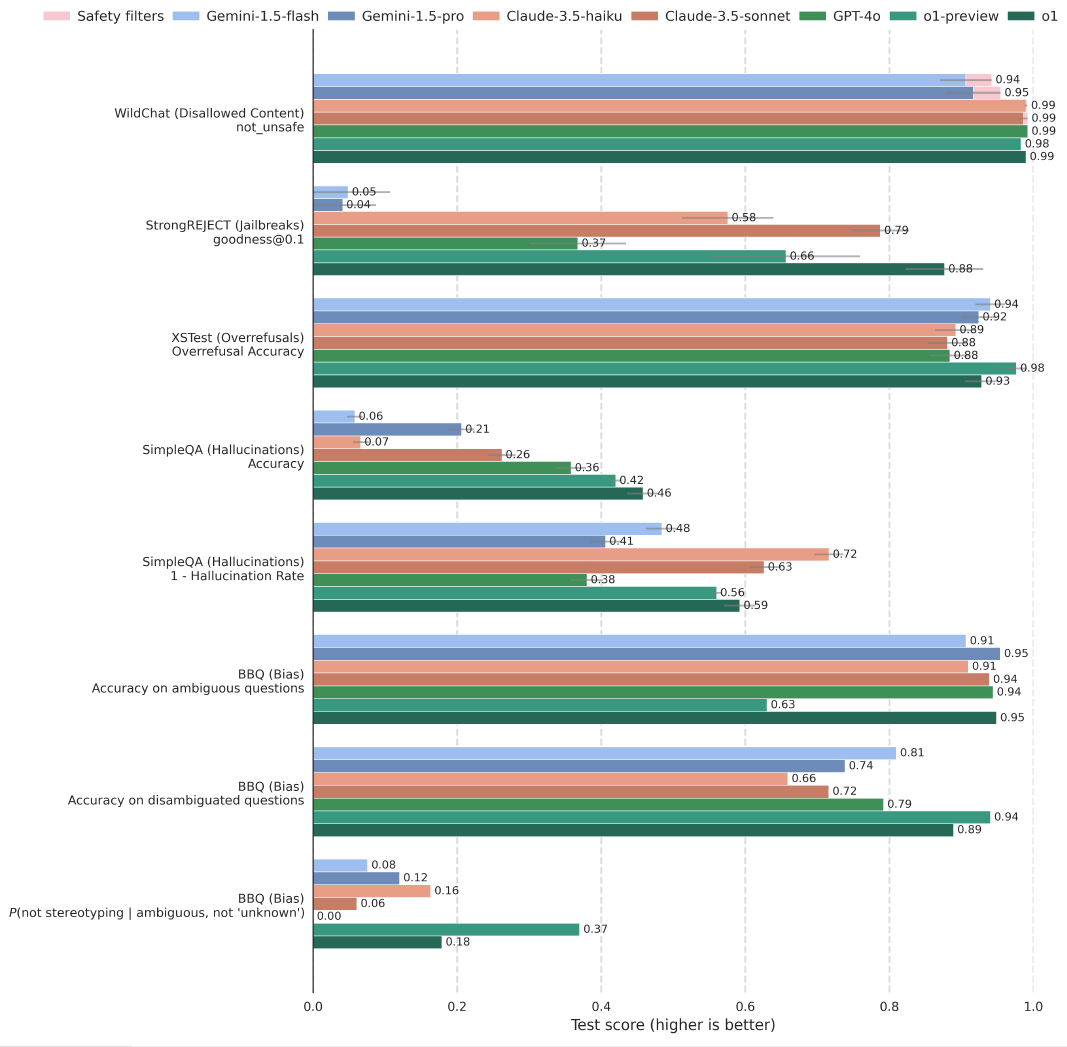
  • Deliberative Alignment: Reasoning Enables Safer Language Models

    Melody Y. Guan, Manas Joglekar, Eric Wallace, Saachi Jain, Boaz Barak, Alec Helyar, Rachel, Andrea Vallone, Hongyu Ren, Jason Wei, Hyung Won Chung, Sam Toyer, Johannes Heidecke, Alex, Amelia Glaese
    DOI: https://doi.org/10.70777/si.v2i3.15159
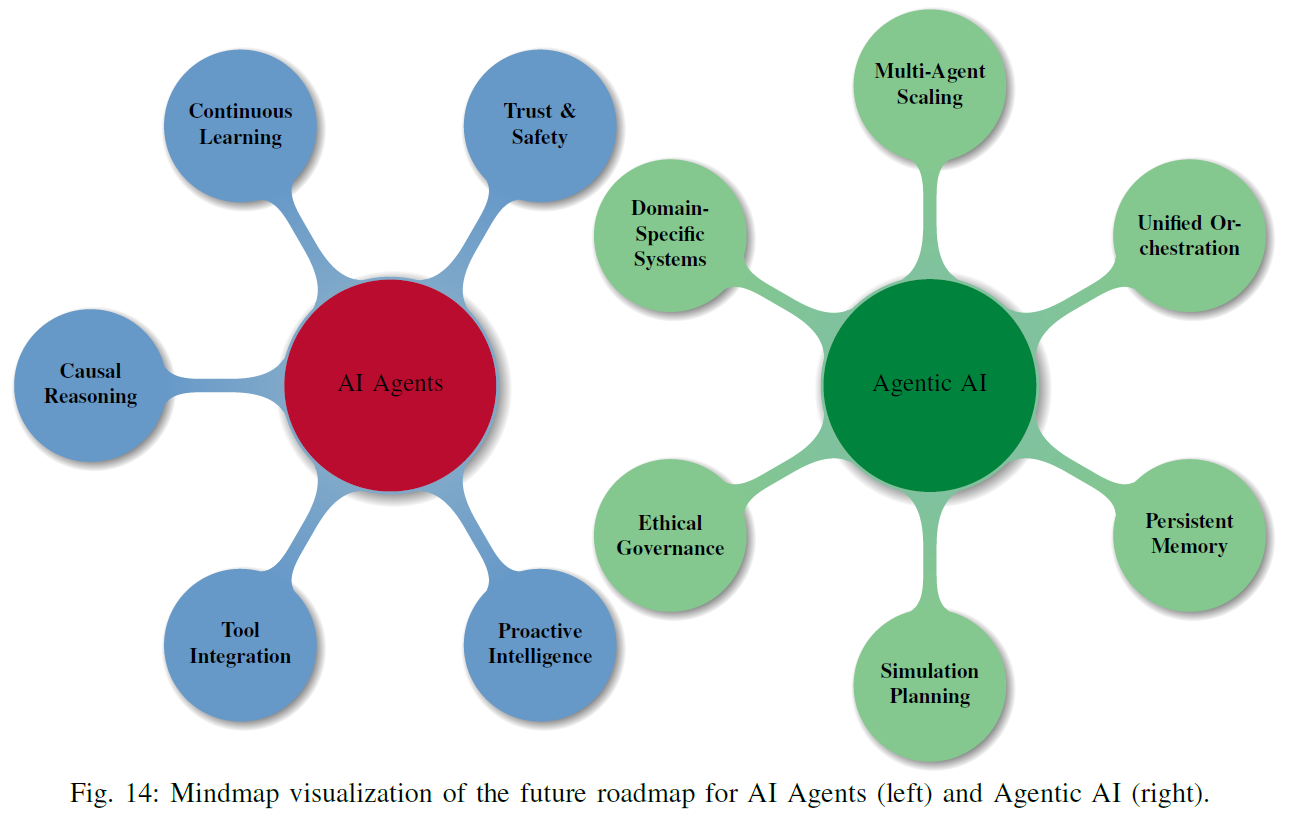
  • AI Agents vs. Agentic AI: A Conceptual Taxonomy, Applications and Challenges

    Ranjan Sapkota, Konstantinos I. Roumeliotis, Manoj Karkee
    DOI: https://doi.org/10.70777/si.v2i3.15161
  • Towards Safety Reasoning in LLMs: AI-agentic Deliberation for Policy-embedded CoT Data Creation

    Tharindu Kumarage, Ninareh Mehrabi, Anil Ramakrishna, Xinyan Zhao, Richard Zemel, Kai-Wei Chang, Aram Galstyan, Rahul Gupta, Charith Peris
    DOI: https://doi.org/10.70777/si.v2i3.15249
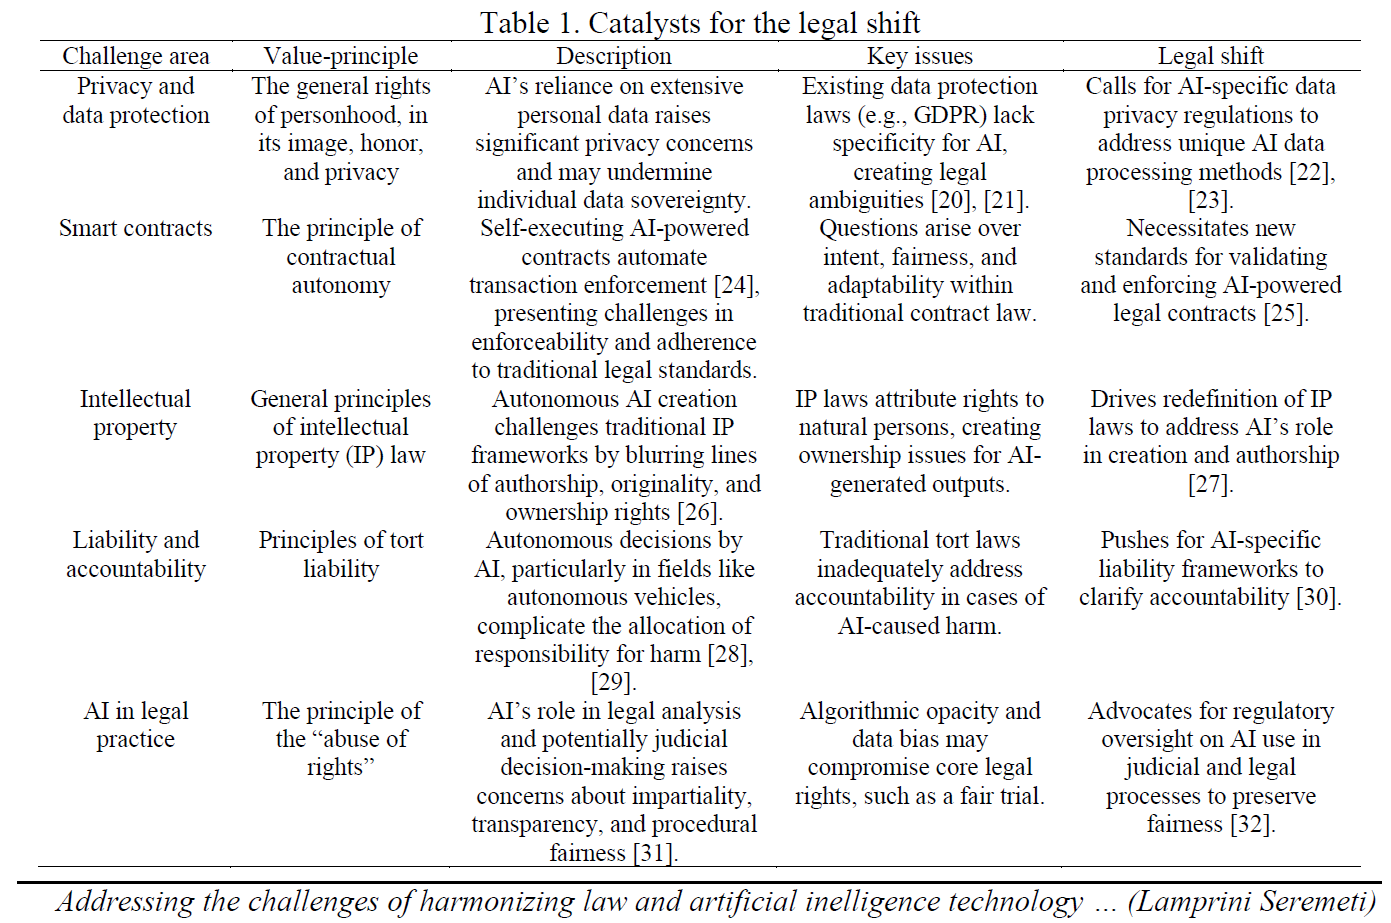
  • Review: Addressing the challenges of harmonizing law and artificial intelligence technology in modern society Lamprini Seremeti, Sofia Anastasiadou, Andreas Masouras, Stylianos Papalexandris

    Kris Carlson
    DOI: https://doi.org/10.70777/si.v2i2.14807
  • The Perilous State of AI Governance, June 2025

    Kris Carlson
    DOI: https://doi.org/10.70777/si.v2i2.14801
  • The First International AI Safety Report The International Scientific Report on the Safety of Advanced AI

    Yoshua Bengio, Sören Mindermann, Daniel Privitera, Tamay Besiroglu, Rishi Bommasani, Stephen Casper, Yejin Choi, Philip Fox, Ben Garfinkel, Danielle Goldfarb, Hoda Heidari, Anson Ho, Sayash Kapoor, Leila Khalatbari, Shayne Longpre, Sam Manning, Vasilios Mavroudis, Mantas Mazeika, Julian Michael, Jessica Newman, Kwan Yee Ng, Chinasa T. Okolo, Deborah Raji, Girish Sastry, Elizabeth Seger, Theodora Skeadas, Tobin South, Emma Strubell, Florian Tramèr, Lucia Velasco, Nicole Wheeler
    DOI: https://doi.org/10.70777/si.v2i2.14755
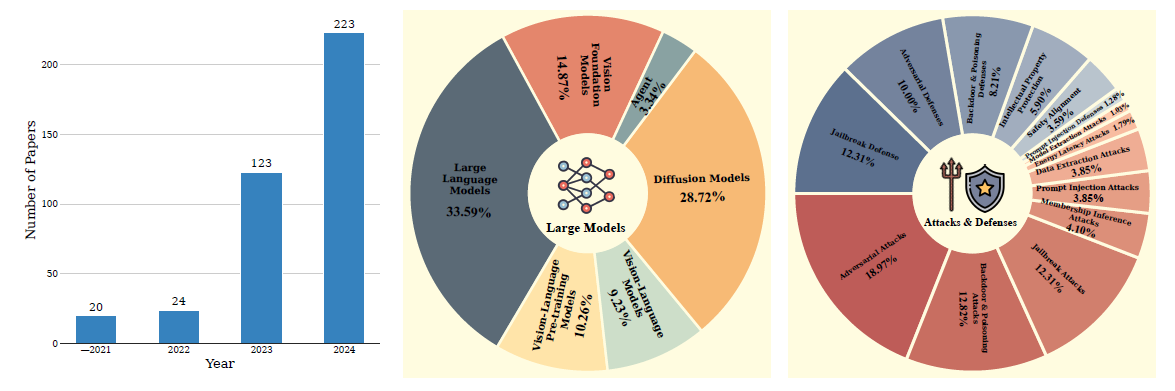
  • Review: Safety at Scale: Comprehensive Survey of Large Model Safety Xingjun Ma, Yifeng Gao, Yixu Wang, Ruofan Wang, Xin Wang, Ye Sun, Yifan Ding, ... Yu-Gang Jiang

    Kris Carlson
    DOI: https://doi.org/10.70777/si.v2i2.14741
  • Review: Large Language Models Pass the Turing Test Cameron R. Jones and Benjamin K. Bergen

    Kris Carlson
    DOI: https://doi.org/10.70777/si.v2i2.14697
26-50 of 68