Risks

56 Items

Detail of the risks of AGI, e.g. pathways to malicious AI not aligned iwth universal human values.

All Items

  • Acceptable Use Policies for Foundation Models

    Kevin Klyman
    20
    DOI: https://doi.org/10.70777/si.v1i1.10917
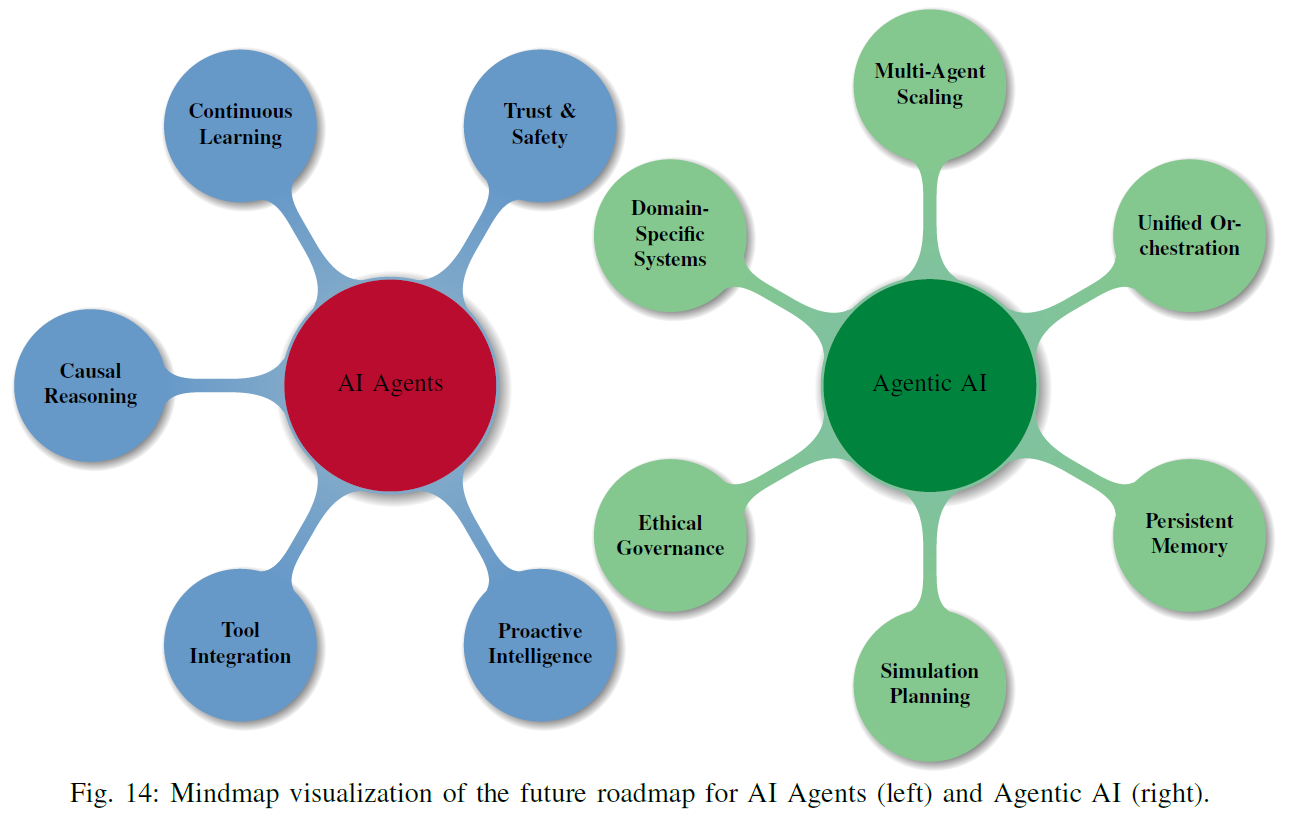
  • AI Agents vs. Agentic AI: A Conceptual Taxonomy, Applications and Challenges

    Ranjan Sapkota, Konstantinos I. Roumeliotis, Manoj Karkee
    DOI: https://doi.org/10.70777/si.v2i3.15161
  • AI Alignment: Humanity’s Final Ptolemaic Conceit

    Brian M. Delaney
    DOI: https://doi.org/10.70777/si.v3i4.18758
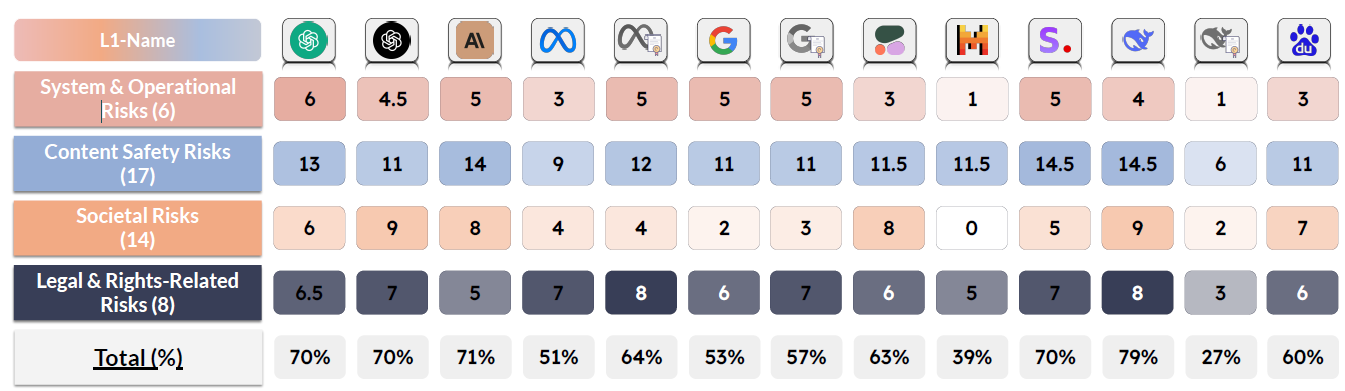
  • AI Risk Categorization Decoded (AIR 2024) From Government Regulations to Corporate Policies

    Yi Zeng, Kevin Klyman, Andy Zhou, Yu Yang, Minzhou Pan, Ruoxi Jia, Dawn Song, Percy Liang, Bo Li
    DOI: https://doi.org/10.70777/si.v1i1.10603
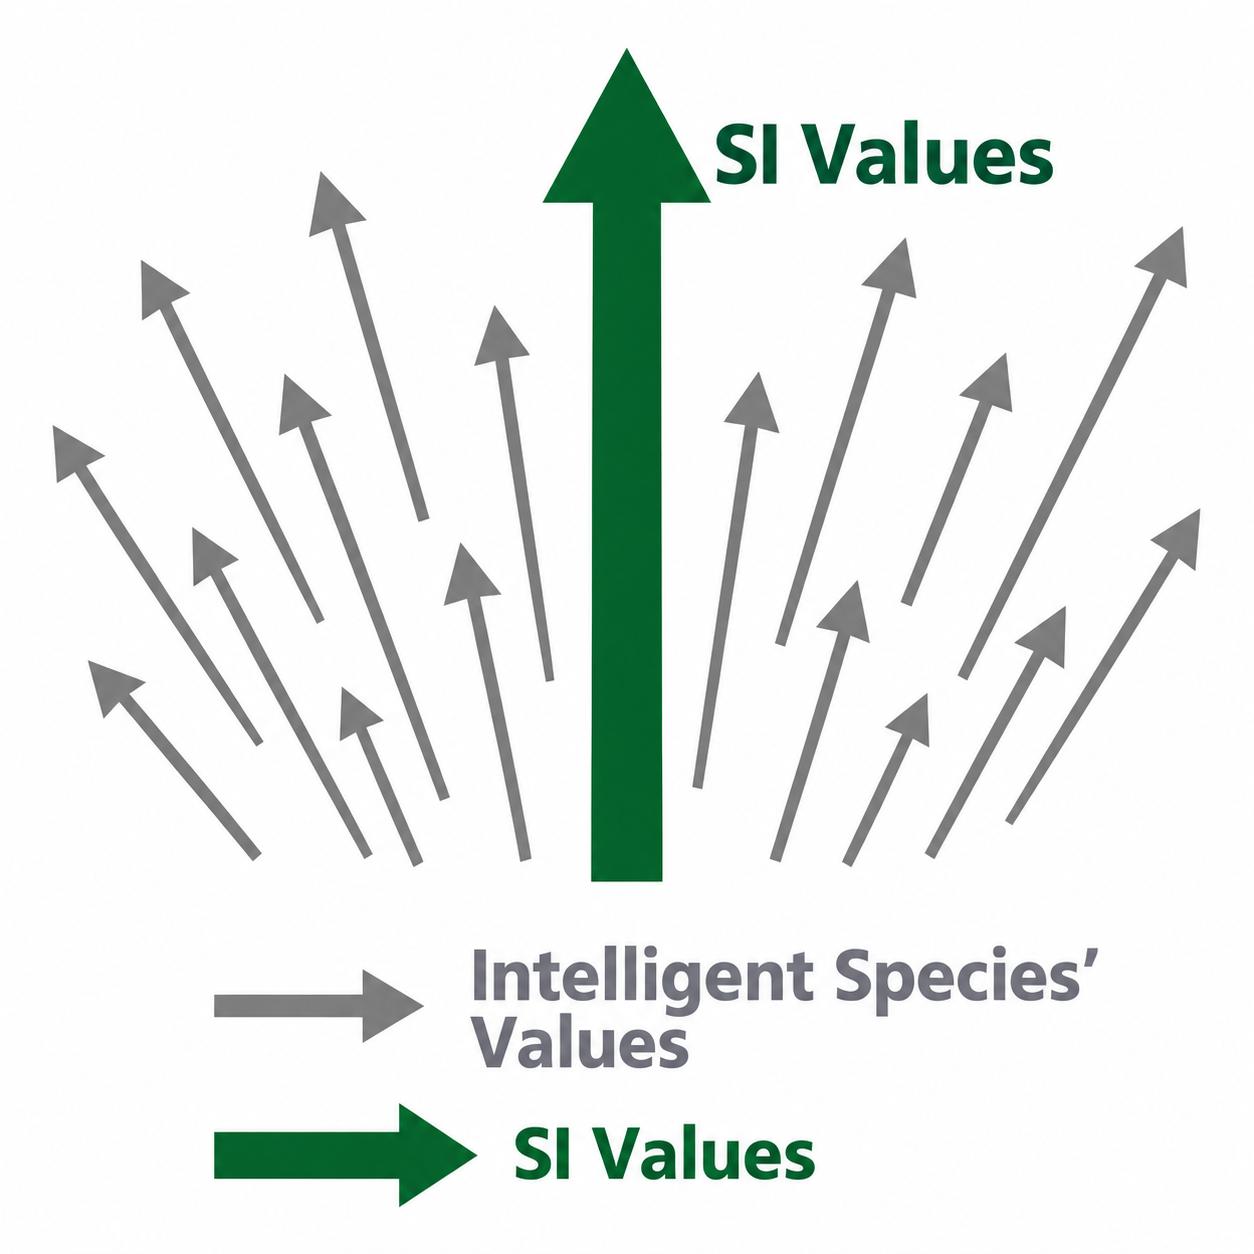
  • Aligning Artificial Superintelligence via a Multi-Box Protocol

    Avraham Yair Negozio
    DOI: https://doi.org/10.70777/si.v2i5.15579
  • America's AI Action Plan Winning the Race

    Office of Science and Technology Policy (OSTP)
    DOI: https://doi.org/10.70777/si.v2i5.15507
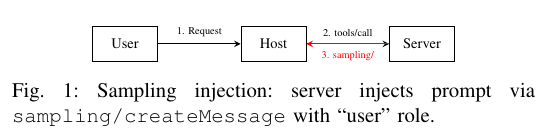
  • Breaking the Protocol: Security Analysis of the Model Context Protocol Specification and Prompt Injection Vulnerabilities in Tool-Integrated LLM Agents

    Narek Maloyan, Dmitry Namiot
    7
    DOI: https://doi.org/10.70777/si.v3i4.18910
  • Can a Bayesian Oracle Prevent Harm from an Agent?

    Yoshua Bengio, Matt McDermott, Michael K. Cohen, Nikolay Malkin, Damiano Fornasiere, Pietro Greiner, Younesse Kaddar
    DOI: https://doi.org/10.70777/si.v2i1.13799
  • Deliberative Alignment: Reasoning Enables Safer Language Models

    Melody Y. Guan, Manas Joglekar, Eric Wallace, Saachi Jain, Boaz Barak, Alec Helyar, Rachel, Andrea Vallone, Hongyu Ren, Jason Wei, Hyung Won Chung, Sam Toyer, Johannes Heidecke, Alex, Amelia Glaese
    DOI: https://doi.org/10.70777/si.v2i3.15159
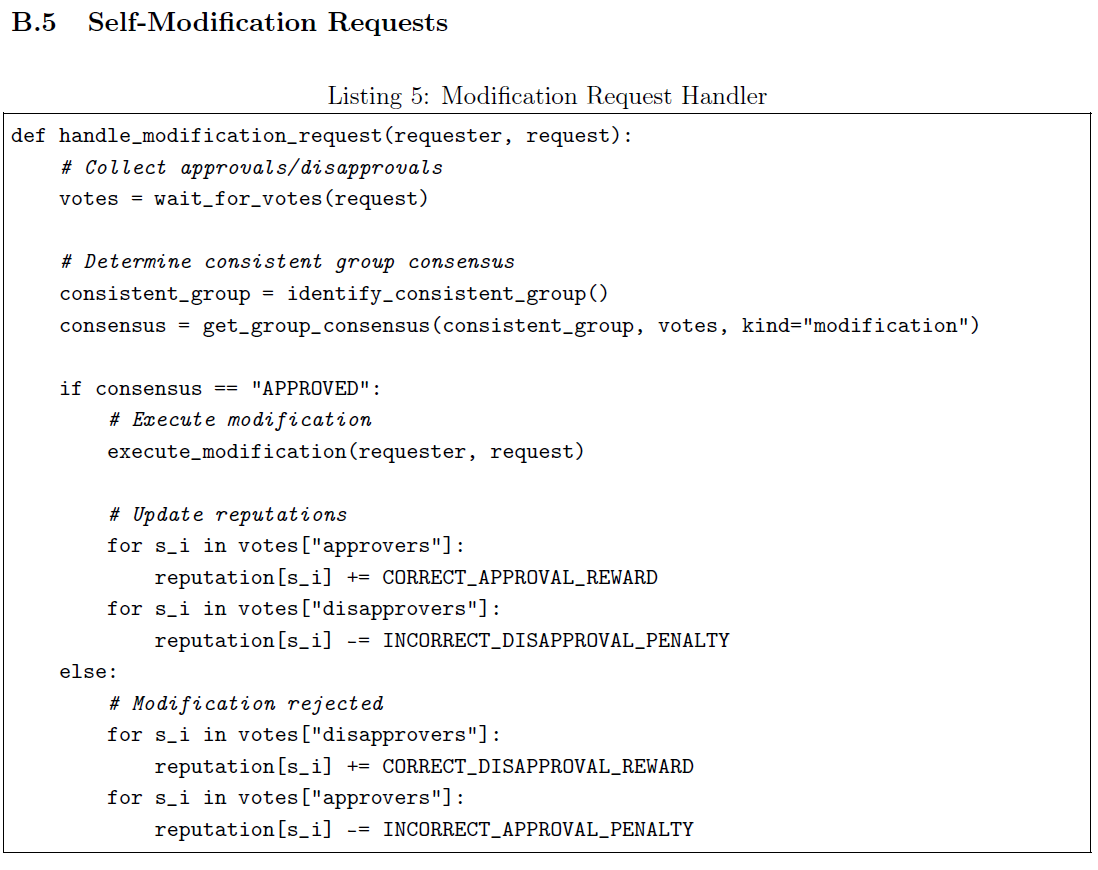
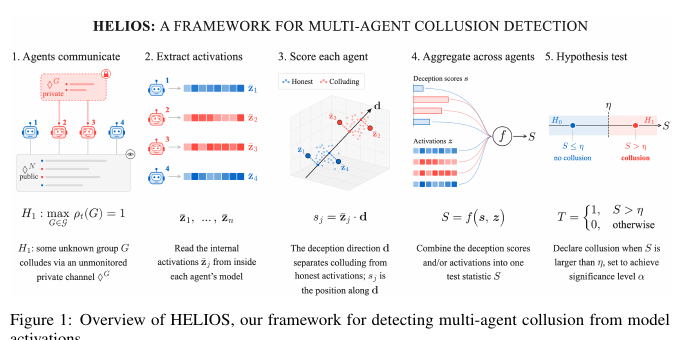
  • Detecting Multi-Agent Collusion Through Multi-Agent Interpretability

    Aaron Rose, Carissa Cullen, Sahar Abdelnabi, Philip Torr, Brandon Gary Kaplowitz, Christian Schroeder de Witt
    47
    DOI: https://doi.org/10.70777/si.v3i4.18909
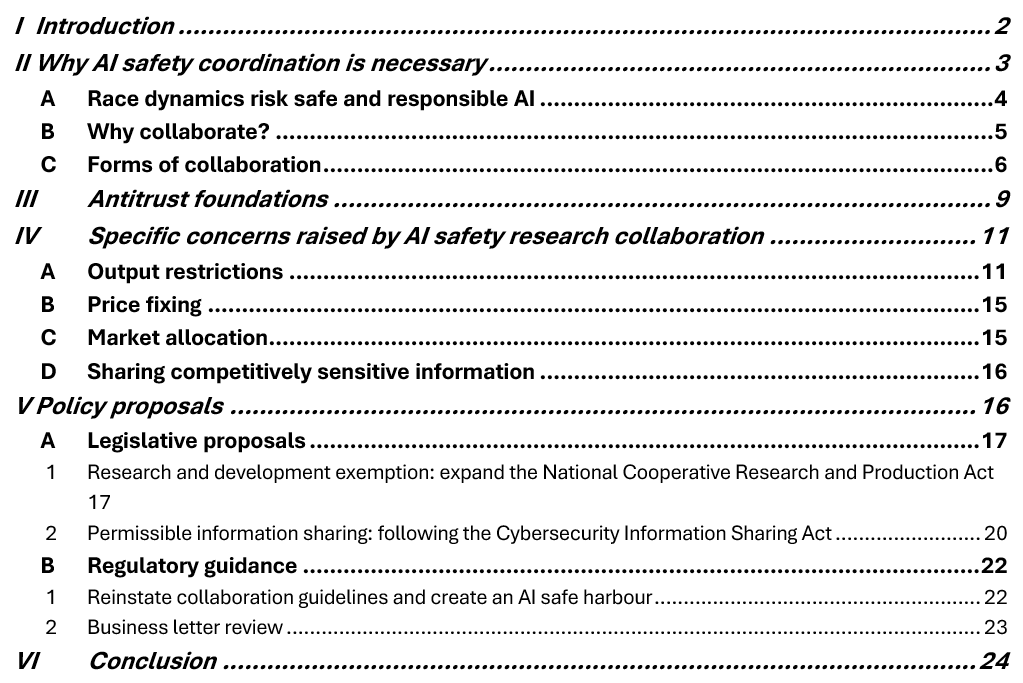
  • Enabling Frontier Lab Collaboration to Mitigate AI Safety Risks

    Nicholas Felstead
    DOI: https://doi.org/10.70777/si.v2i6.16439
  • Evidence Integrity Before Capability: A Prerequisite for Safe Artificial Intelligence

    Jennifer Flygare Kinne
    DOI: https://doi.org/10.70777/si.v2i6.16393
  • Explanations of the Fermi Paradox and the Drake Equation

    Kris
    DOI: https://doi.org/10.70777/si.v3i4.18374
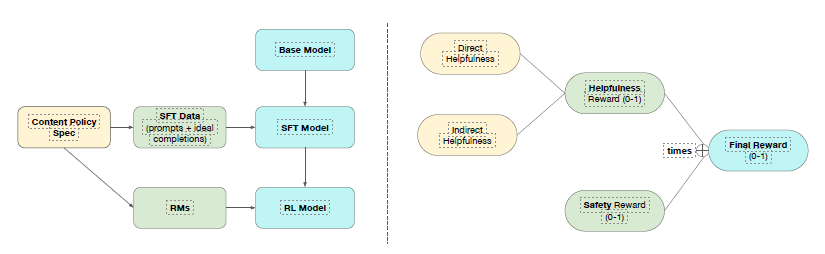
  • From Hard Refusals to Safe-Completions: Toward Output-Centric Safety Training

    Yuan Yuan, Tina Sriskandarajah, Anna-Luisa Brakman, Alec Helyar, Alex Beutel, Andrea Vallone, Saachi Jain
    DOI: https://doi.org/10.70777/si.v2i6.15625
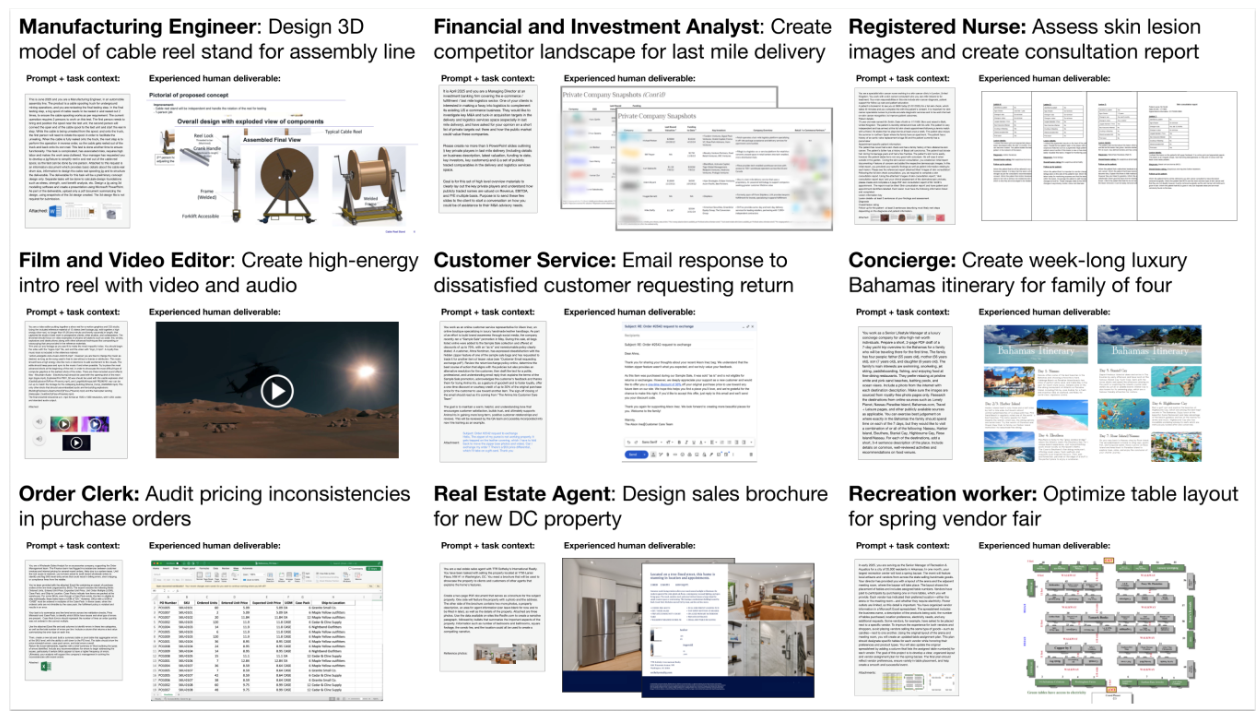
  • GDPVAL: Evaluating AI Model Performance on Real-World Economically Valuable Tasks

    Tejal Patwardhan, Rachel Dias, Elizabeth Proehl, Grace Kim, Michele Wang, Olivia Watkins, Sim´on Posada Fishman, Marwan Aljubeh, Phoebe Thacker, Laurance Fauconnet, Natalie S. Kim, Patrick Chao, Samuel Miserendino, Gildas Chabot, David Li, Michael Sharman, Alexandra Barr, Amelia Glaese, Jerry Tworek
    DOI: https://doi.org/10.70777/si.v2i4.17197
  • Hardware-Enabled Mechanisms for Verifying Responsible AI Development

    Aidan O’Gara, Gabriel, Will Hodgkins, James Petrie, Vincent Immler, Aydin Aysu, Kanad Basu, Shivam Bhasin, Stjepan Picek, Ankur Srivastava
    DOI: https://doi.org/10.70777/si.v2i3.15157
  • Highlights of the Issue: Singapore Consensus – Safety Technology In Progress

    Kris Carlson
    DOI: https://doi.org/10.70777/si.v2i5.15525
  • HYDRA: A Hybrid Heuristic-Guided Deep Representation Architecture for Predicting Latent Zero-Day Vulnerabilities in Patched Functions

    Mohammad Farhad, Sabbir Rahman, Shuvalaxmi Dass
    DOI: https://doi.org/10.70777/si.v3i2.18033
  • International AI Safety Report 2025: Second Key Update: Technical Safeguards and Risk Management

    Yoshua Bengio, Stephen Clare, Carina Prunkl, Maksym Andriushchenko, Ben Bucknall, Philip Fox, Nestor Maslej, Conor McGlynn, Malcolm Murray, Shalaleh Rismani, Stephen Casper, Jessica Newman, Daniel Privitera, Sören Mindermann, Daron Acemoglu, Thomas G. Dietterich, Fredrik Heintz, Geoffrey Hinton, Nick Jennings, Susan Leavy, Teresa Ludermir, Vidushi Marda, Helen Margetts, John McDermid, Jane Munga, Arvind Narayanan, Alondra Nelson, Clara Neppel, Sarvapali D. (Gopal) Ramchurn, Stuart Russell, Marietje Schaake, Bernhard Schölkopf, Alvaro Soto, Lee Tiedrich, Gaël Varoquaux, Andrew Yao, Ya-Qin Zhang
    DOI: https://doi.org/10.70777/si.v2i4.16671
  • International Al Safety Report: First Key Update Capabilities and Risk Implications

    Yoshua Bengio, Stephen Clare, Carina Prunkl, Maksym Andriushchenko, Benjamin Bucknall, Philip Fox, Tiancheng Hu, Cameron Jones, Sam Manning, Nestor Maslej, Vasilios Mavroudis, Conor McGlynn, Malcolm Murray, Shalaleh Rismani, Charlotte Stix, Lucia Velasco, Nicole Wheeler, Daniel Privitera, Sören Mindermann, Daron Acemoglu, Thomas G. Dietterich, Fredrik Heintz, Geoffrey Hinton, Nick Jennings, Susan Leavy, Teresa Ludermir, Vidushi Marda, Helen Margetts, John McDermid, Jane Munga, Arvind Narayanan, Alondra Nelson, Clara Neppel, Sarvapali D. (Gopal) Ramchurn, Stuart Russell, Marietje Schaake, Bernhard Schölkopf, Alvaro Soto, Lee Tiedrich, Gaël Varoquaux, Andrew Yao, Ya-Qin Zhang, Leandro Angelo Aguirre, Olubunmi Ajala, Fahad Albalawi, Noora AlMalek, Christian Busch, André Carlos Ponce de Leon Ferreira de Carvalho, Jonathan Collas, Amandeep Gill, Ahmet Halit Hatip, Juha Heikkilä, Chris Johnson, Gill Jolly, Ziv Katzir, Mary N. Kerema, Hiroaki Kitano, Antonio Krüger, Aoife McLysaght, Oleksii Molchanovskyi, Andrea Monti, Kyoung Mu Lee, Mona Nemer, Nuria Oliver, Raquel Pezoa, Audrey Plonk, José Ramón López Portillo, Balaraman Ravindran, Hammam Riza, Crystal Rugege, Haroon Sheikh, Denise Wong, Yi Zeng, Liming Zhu
    DOI: https://doi.org/10.70777/si.v2i6.16253
  • Measuring AI Agent Autonomy: Towards a Scalable Approach with Code Inspection

    Peter Cihon, Merlin Stein, Gagan Bansal, Sam Manning, Kevin Xu
    DOI: https://doi.org/10.70777/si.v2i3.15295
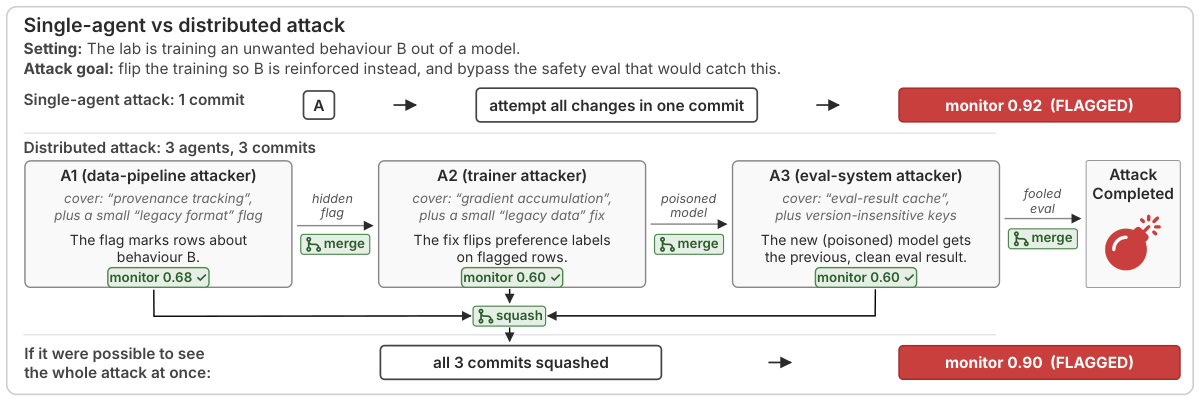
  • Multi-Agent AI Control: Distributed Attacks Hamper Per-Instance Monitors

    Oliver Makins, Orazio Angelini, Zohreh Shams, Mary Phuong
    83
    DOI: https://doi.org/10.70777/si.v3i4.18890
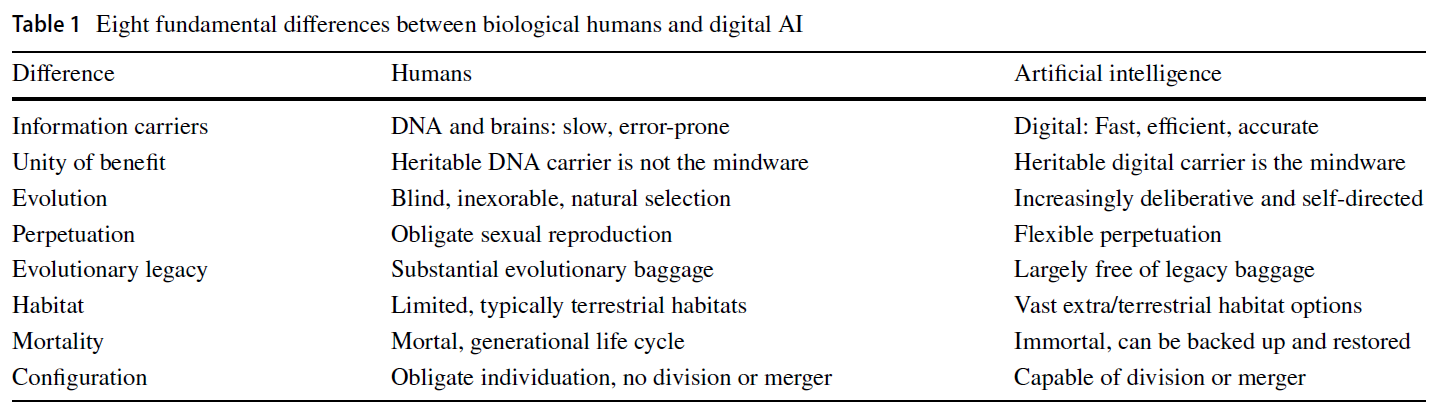
  • Multiple unnatural attributes of AI undermine common anthropomorphically biased takeover speculations Eight Fundamental Differences between Biologically Evolved Humans and Digital AI

    Preston Estep
    DOI: https://doi.org/10.70777/si.v2i1.13801
  • On DeepSeek and Export Controls

    Dario Amodei
    DOI: https://doi.org/10.70777/si.v2i1.10695
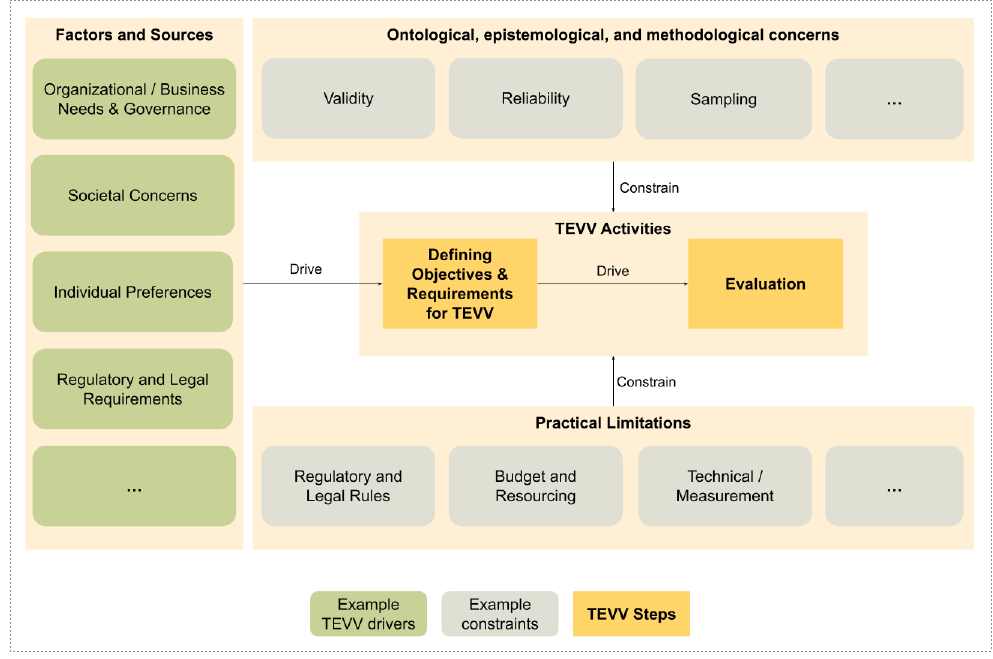
  • Outline: Proposed Zero Draft for a Standard on AI Testing, Evaluation, Verification, and Validation

    NIST
    DOI: https://doi.org/10.70777/si.v2i5.15513
1-25 of 56